Fudan University
I am a Computer Science undergraduate at Fudan University. My research interests center on self-evolving LLM agents, agent memory, and agentic reinforcement learning.
Most recently, I was a research intern at the NUS LV Lab, advised by Prof. Shuicheng Yan, where I studied how agents can learn from experience through coordinated policy learning and memory updates. Previously, I worked on latent memory for long-context reasoning at the FDU FVL Lab and on LLM agents as an LLM Agent Development Intern at Xiaohongshu (RedNote).
Education
-
 Fudan UniversitySep. 2023 - Jun. 2027School of Computer ScienceB.S. in Computer Science
Experience
-
 NUS LV LabMar. 2026 - Jul. 2026Advised by Prof. Shuicheng YanResearch Intern · Self-Evolving Agents
-
 Xiaohongshu (RedNote)Nov. 2025 - Feb. 2026LLM Agent Development Intern
-
FDU FVL LabJun. 2025 - Sep. 2025Advised by Prof. Henghui DingResearch Intern · Latent Memory for LLMs
Honors & Awards
-
Outstanding Student Award with Scholarship2025–2026
News
Selected Publications (view all )
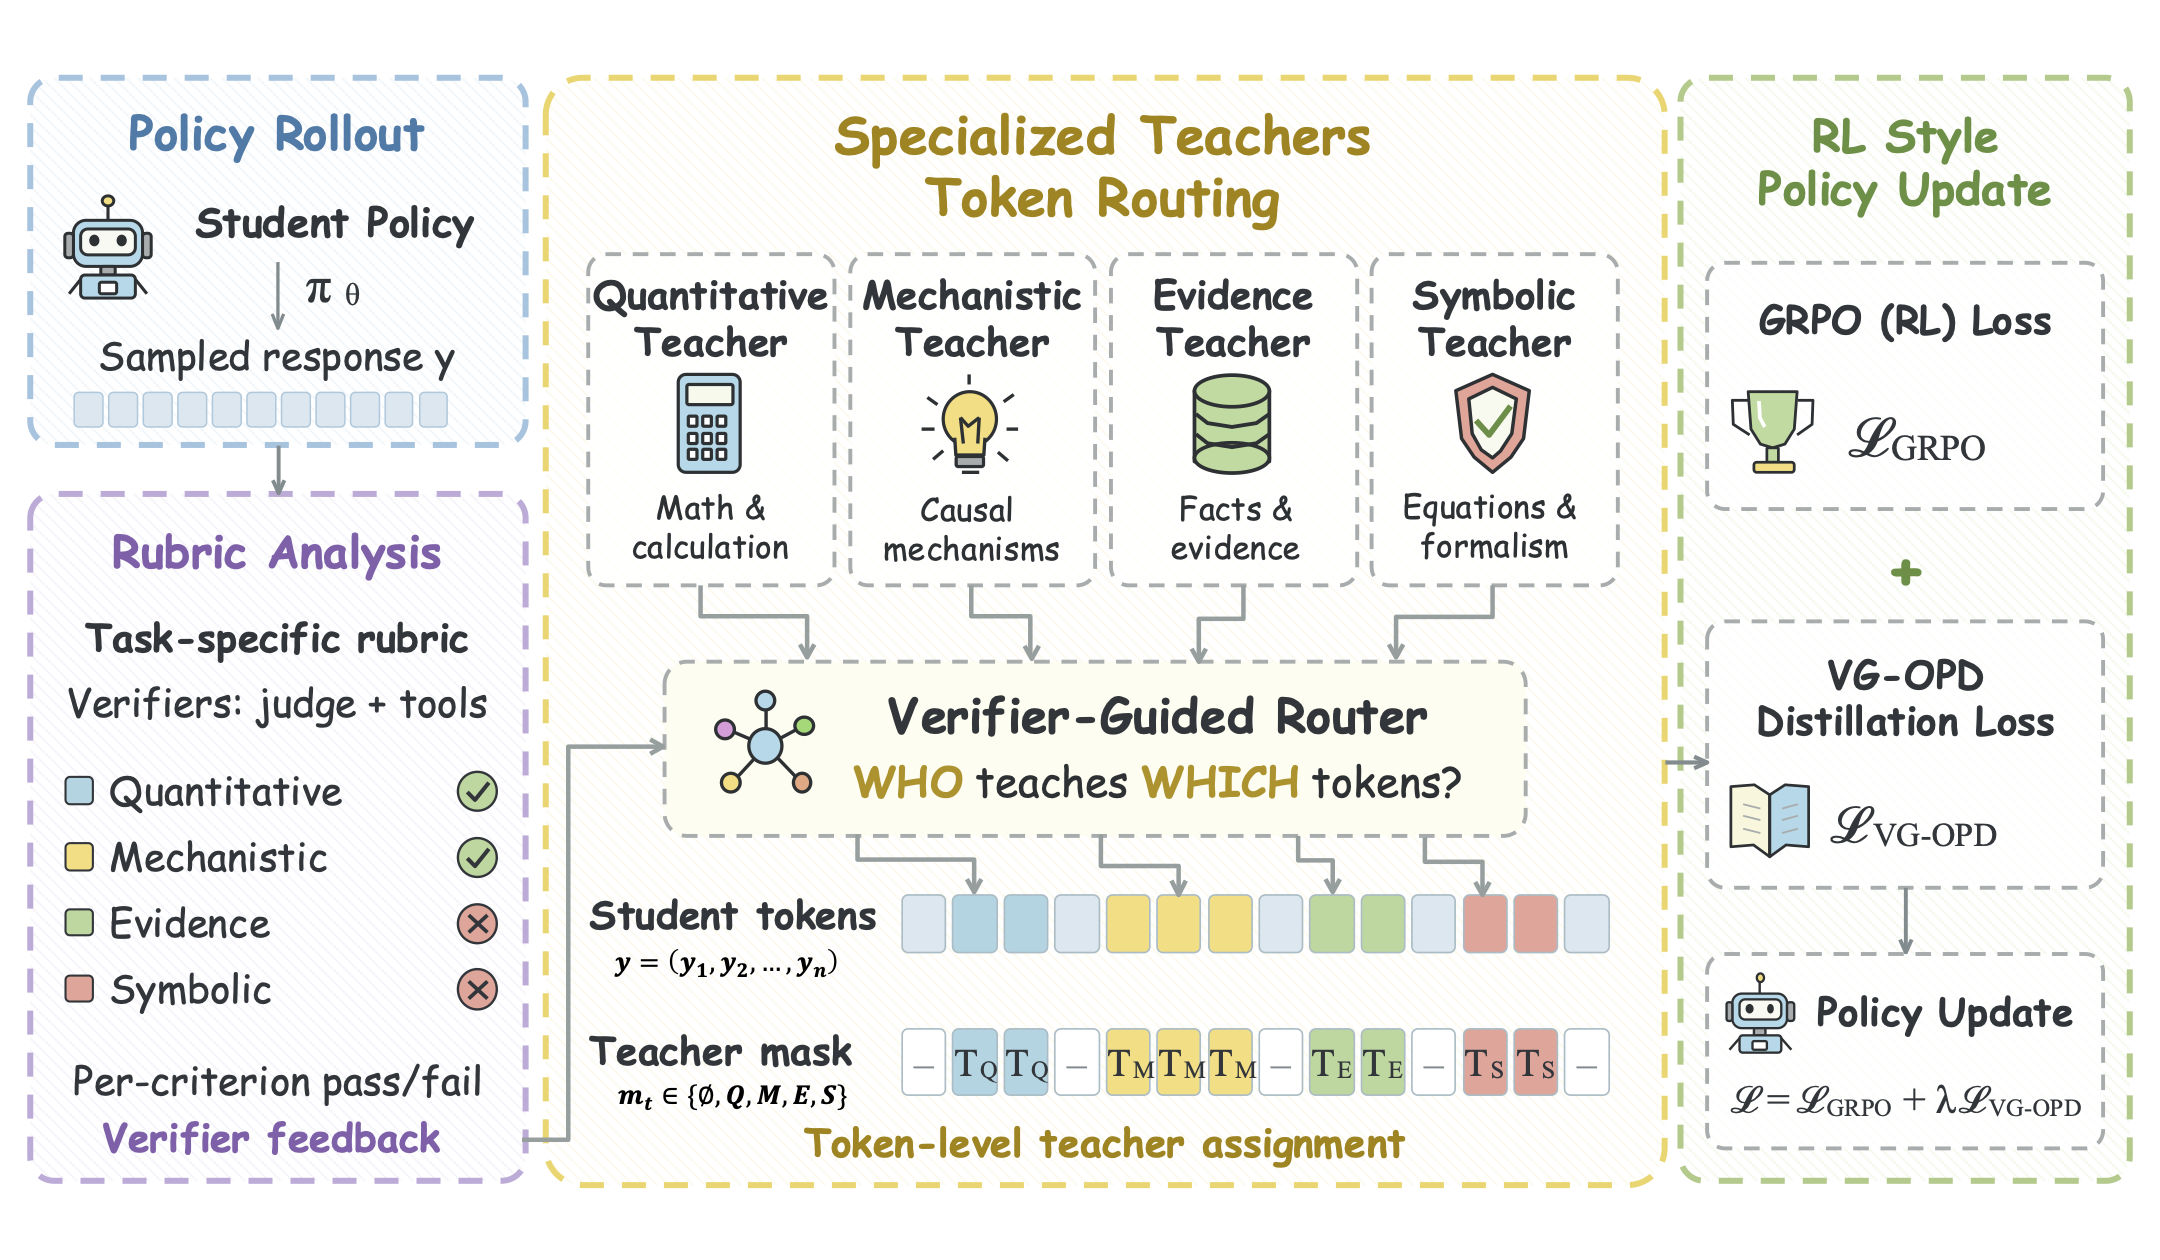
Who Teaches Which Token? Verifier-Gated Multi-Expert On-Policy Distillation for Scientific Reasoning
Xun Xu, Zaixi Zhang
A multi-expert on-policy distillation framework for scientific reasoning that uses verifier feedback to decide which expert should teach each token. VG-OPD localizes and weights expert supervision along the student's reasoning trajectory, improving 4B and 8B students across seven benchmarks.
Who Teaches Which Token? Verifier-Gated Multi-Expert On-Policy Distillation for Scientific Reasoning
Xun Xu, Zaixi Zhang
A multi-expert on-policy distillation framework for scientific reasoning that uses verifier feedback to decide which expert should teach each token. VG-OPD localizes and weights expert supervision along the student's reasoning trajectory, improving 4B and 8B students across seven benchmarks.
OPD-Evolver: Cultivating Holistic Agent Evolver via On-Policy Distillation
Guibin Zhang*, Xun Xu*, Yanwei Yue, Zikun Su, Wangchunshu Zhou, Xiaobin Hu#, Shuicheng Yan# (* equal contribution, # corresponding author)
Conference on Empirical Methods in Natural Language Processing (EMNLP) 2026
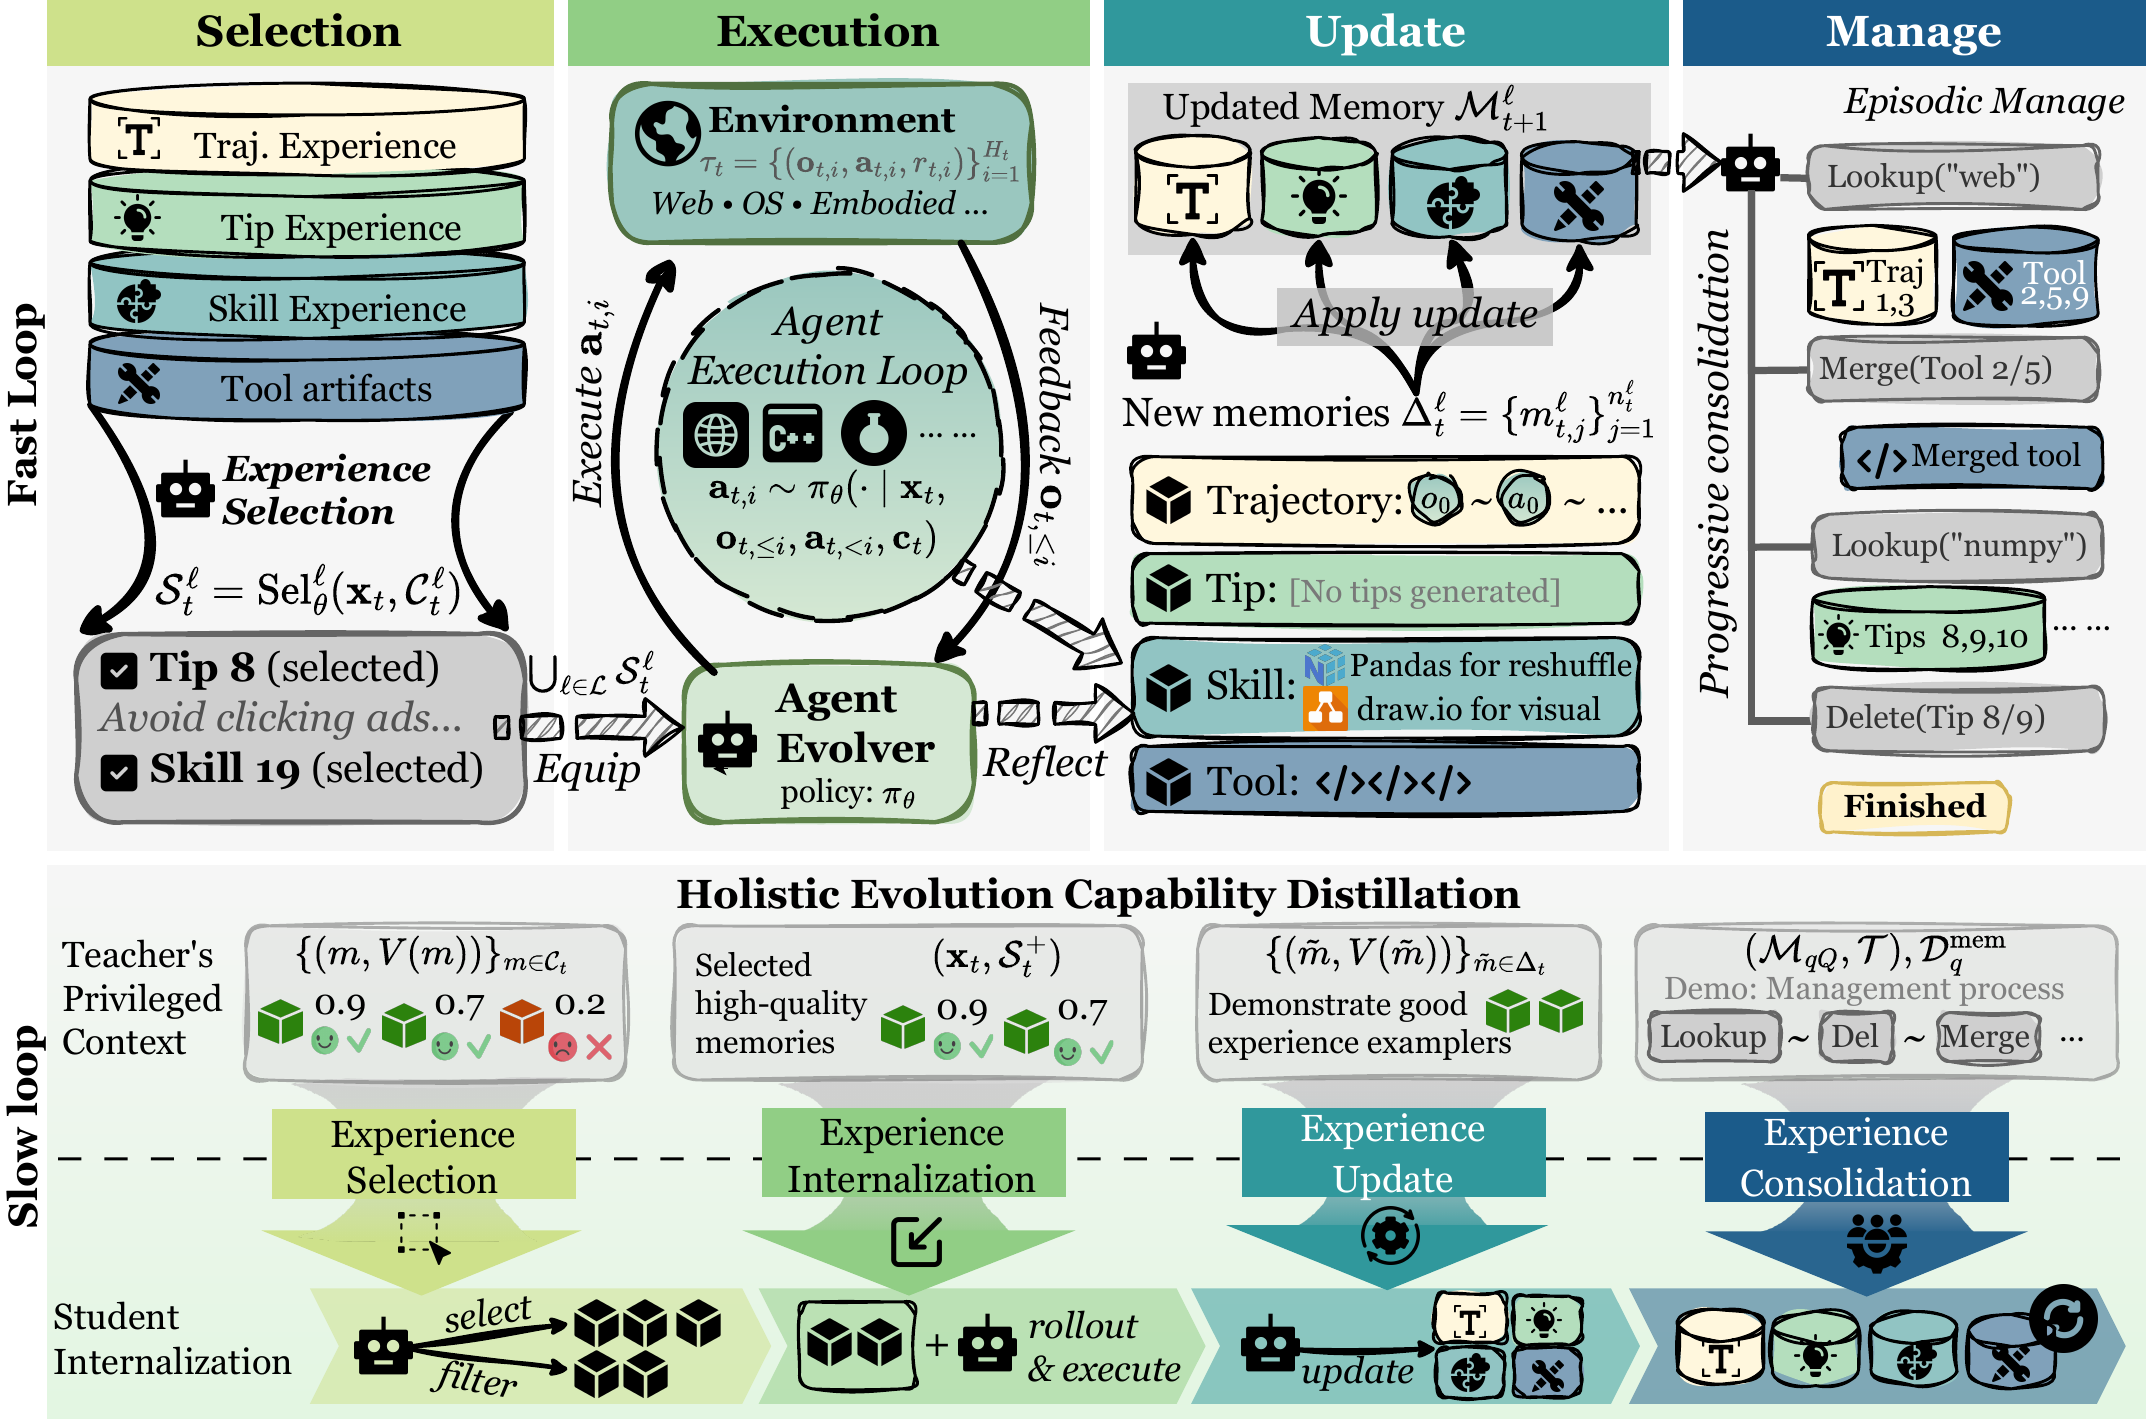
A slow-fast co-evolution framework that teaches agents to improve through experience. OPD-Evolver combines a four-level memory hierarchy with outcome-calibrated attribution and privileged-hindsight distillation.
OPD-Evolver: Cultivating Holistic Agent Evolver via On-Policy Distillation
Guibin Zhang*, Xun Xu*, Yanwei Yue, Zikun Su, Wangchunshu Zhou, Xiaobin Hu#, Shuicheng Yan# (* equal contribution, # corresponding author)
Conference on Empirical Methods in Natural Language Processing (EMNLP) 2026
A slow-fast co-evolution framework that teaches agents to improve through experience. OPD-Evolver combines a four-level memory hierarchy with outcome-calibrated attribution and privileged-hindsight distillation.