2026
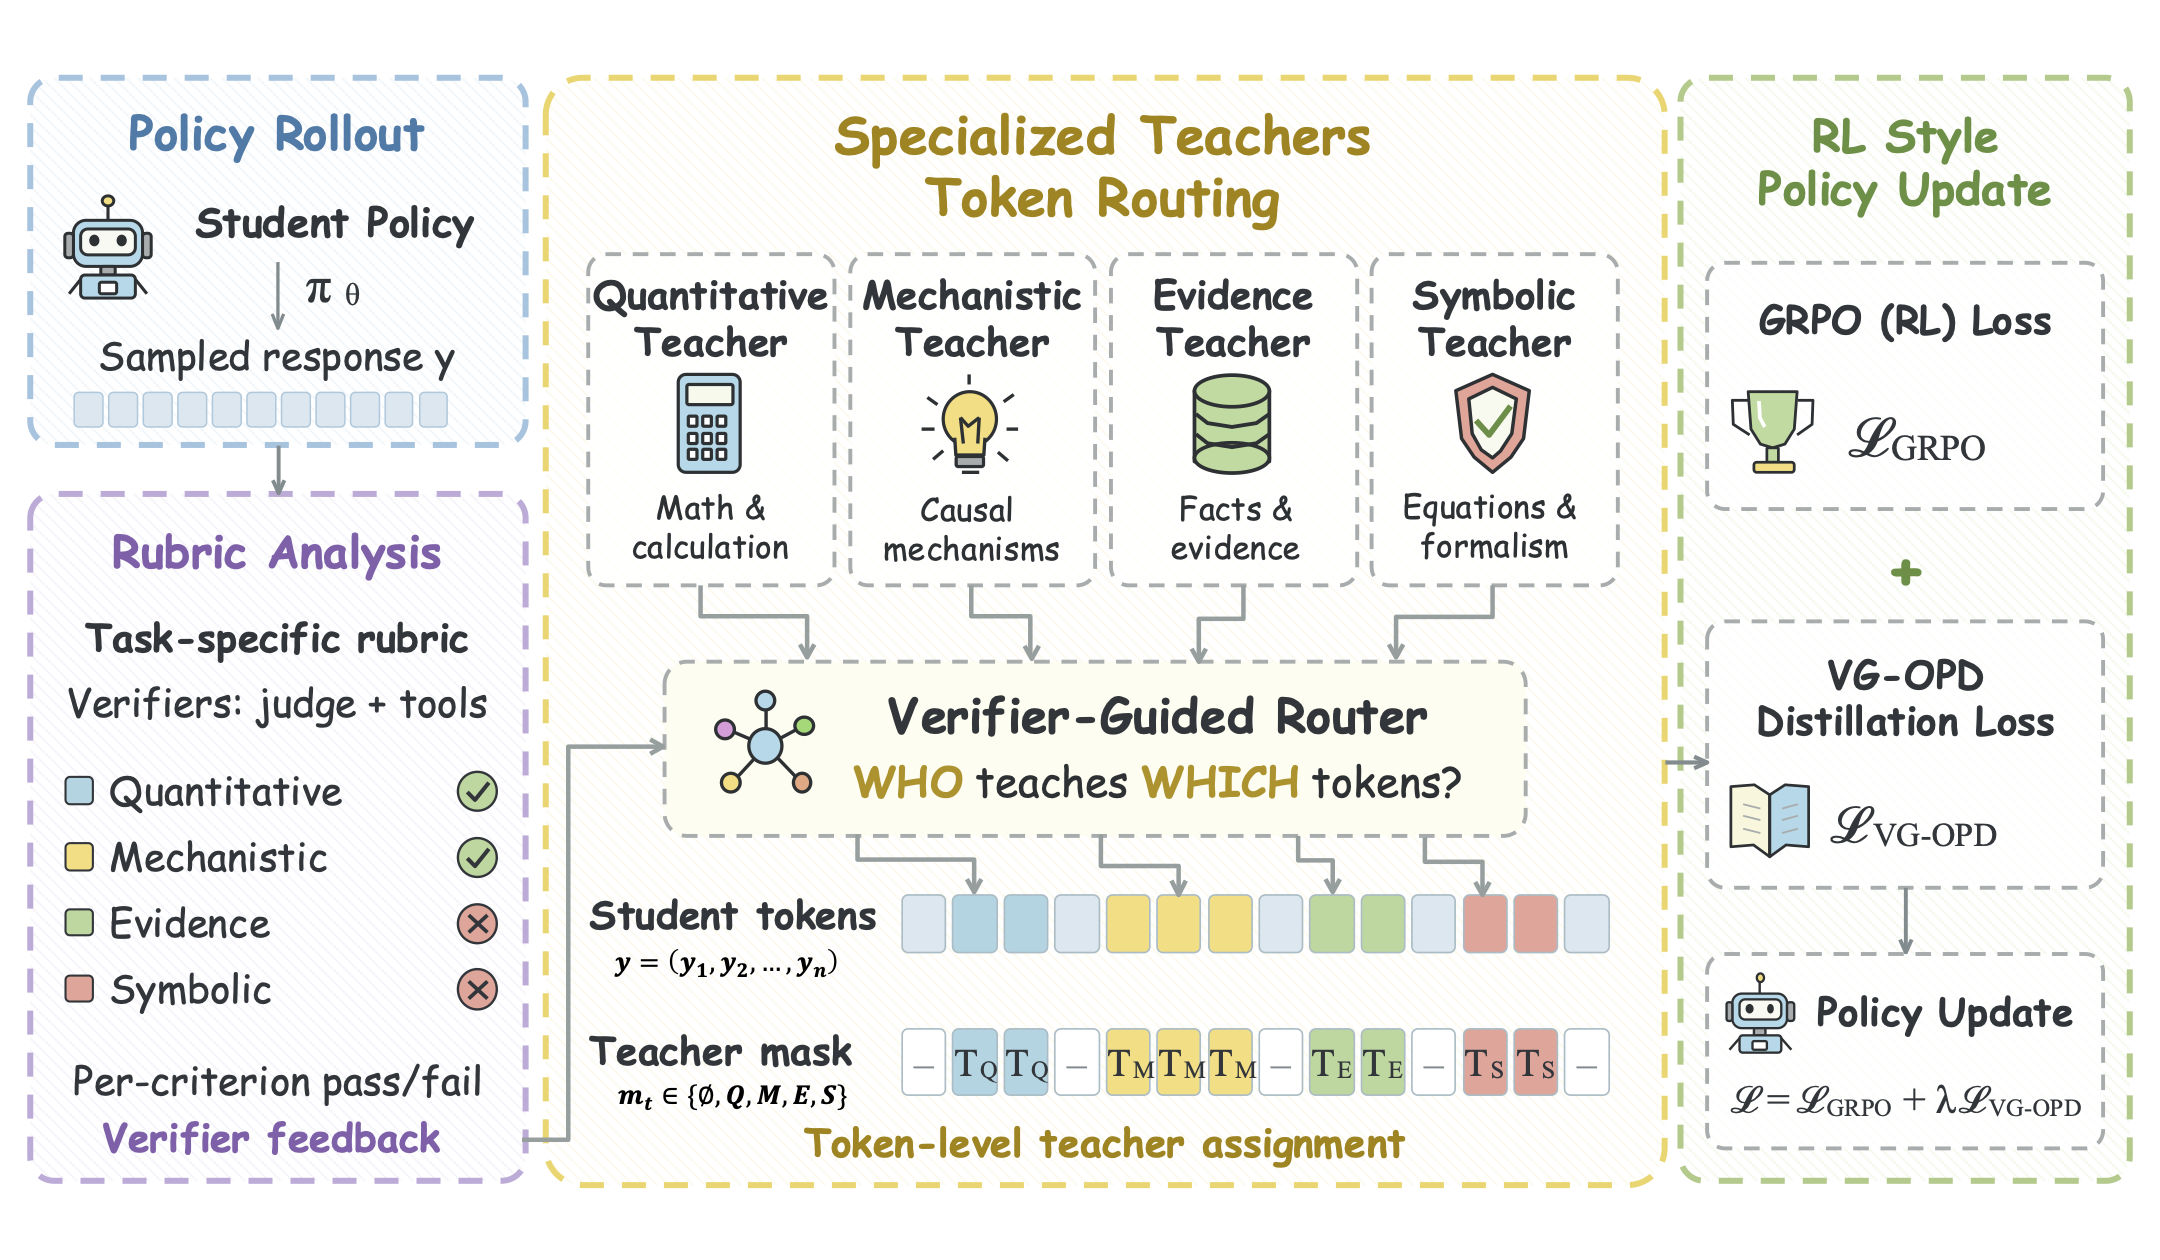
Who Teaches Which Token? Verifier-Gated Multi-Expert On-Policy Distillation for Scientific Reasoning
Xun Xu, Zaixi Zhang
A multi-expert on-policy distillation framework for scientific reasoning that uses verifier feedback to decide which expert should teach each token. VG-OPD localizes and weights expert supervision along the student's reasoning trajectory, improving 4B and 8B students across seven benchmarks.
Who Teaches Which Token? Verifier-Gated Multi-Expert On-Policy Distillation for Scientific Reasoning
Xun Xu, Zaixi Zhang
A multi-expert on-policy distillation framework for scientific reasoning that uses verifier feedback to decide which expert should teach each token. VG-OPD localizes and weights expert supervision along the student's reasoning trajectory, improving 4B and 8B students across seven benchmarks.
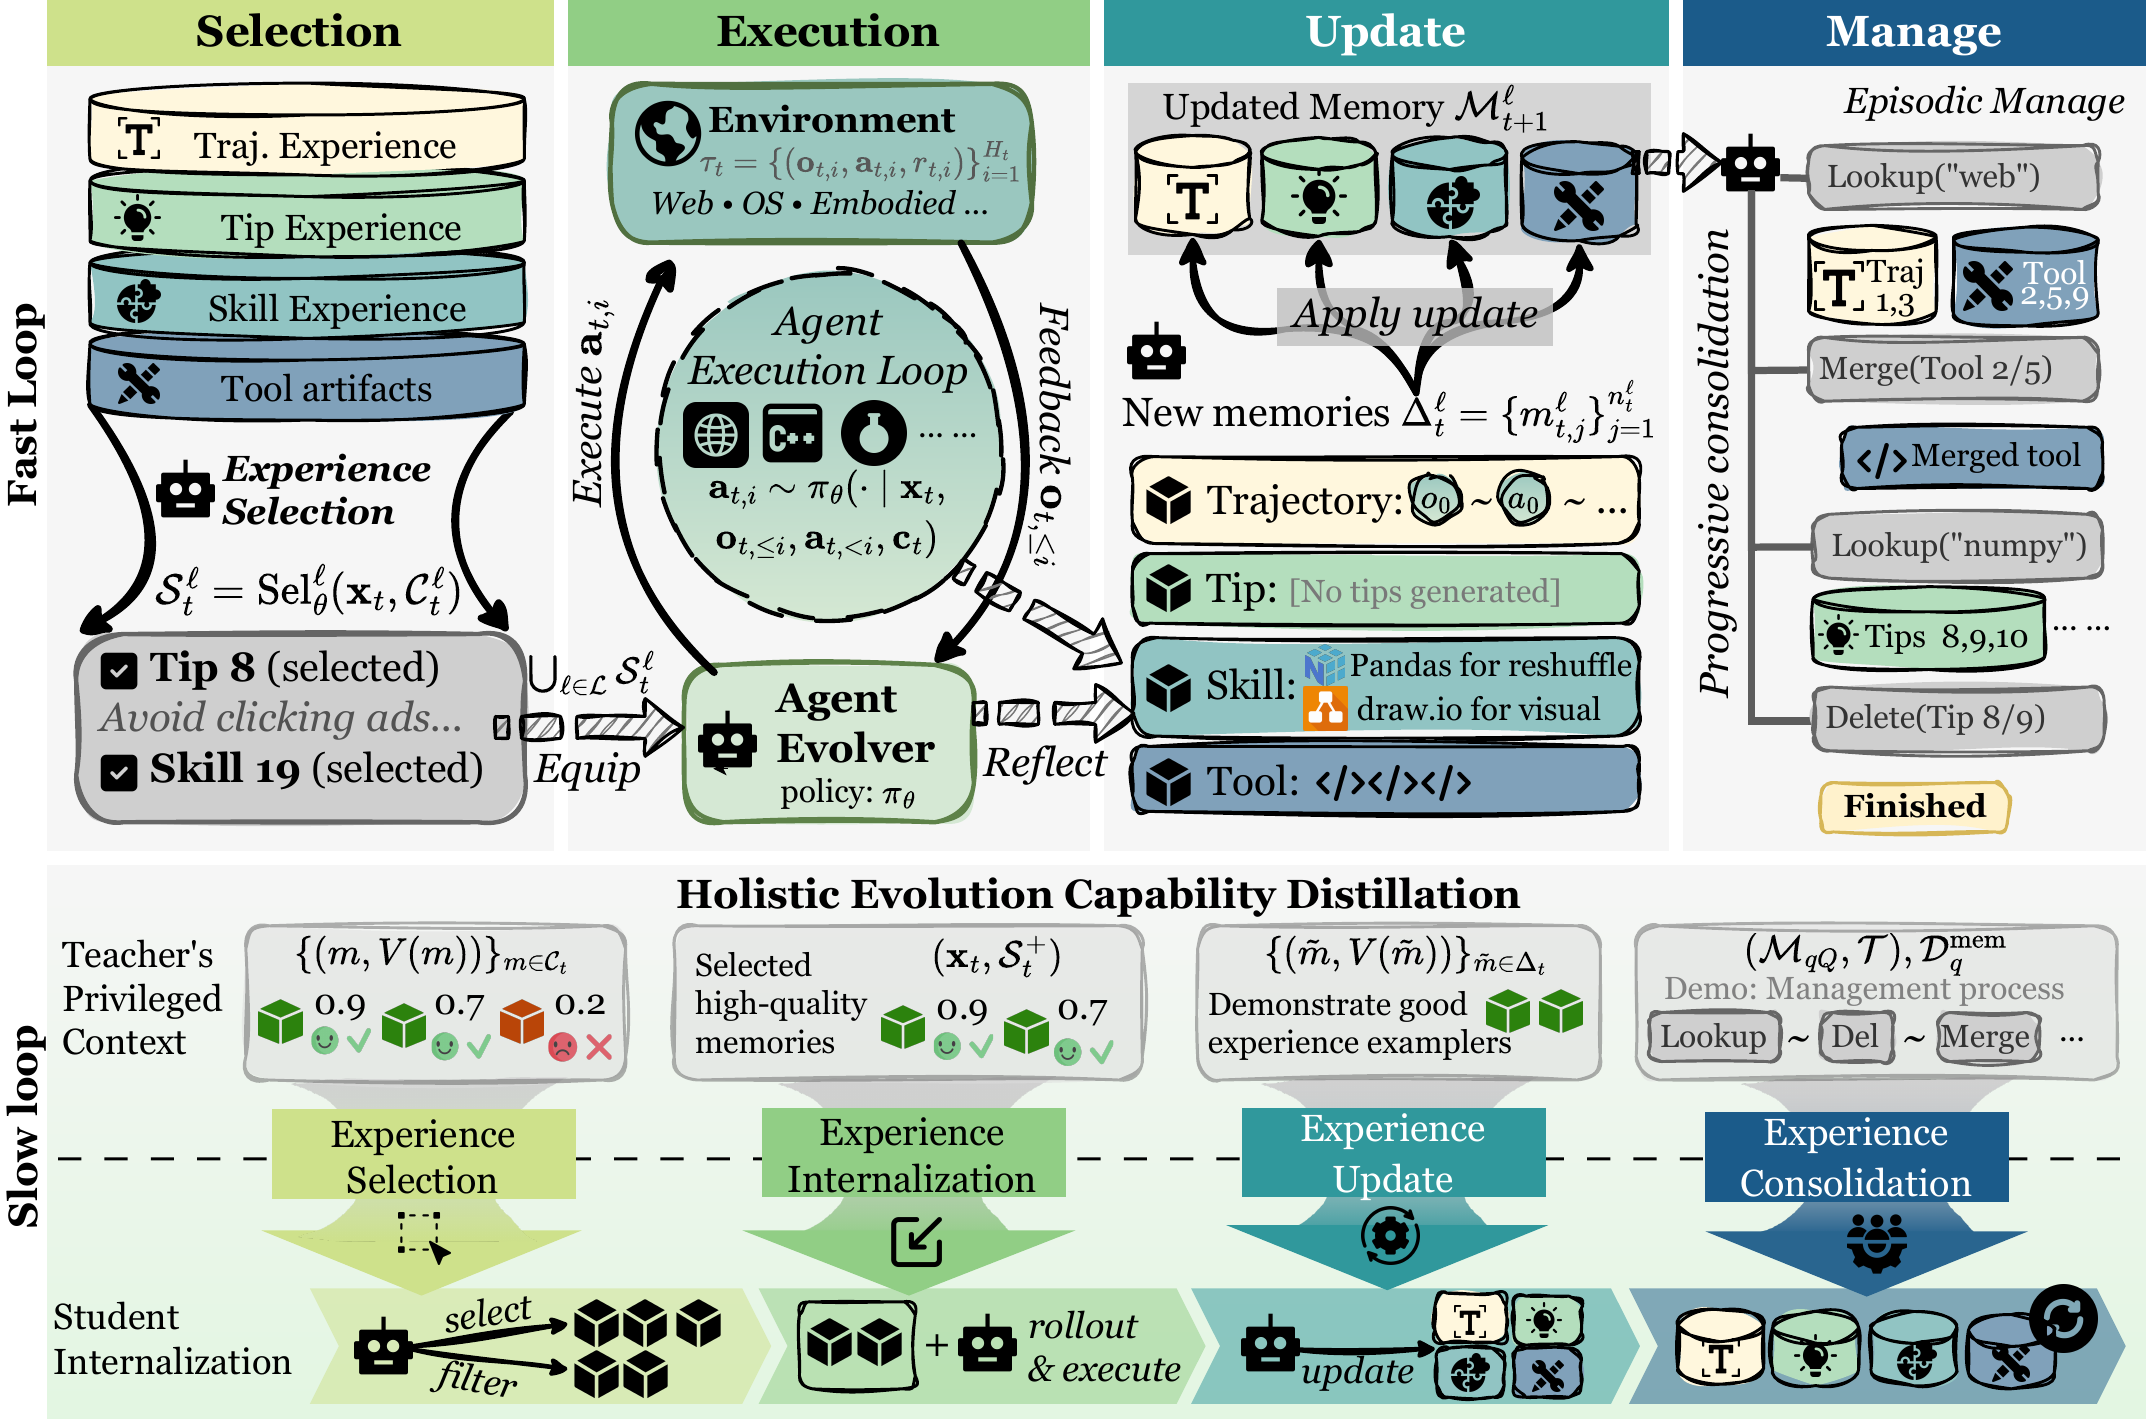
OPD-Evolver: Cultivating Holistic Agent Evolver via On-Policy Distillation
Guibin Zhang*, Xun Xu*, Yanwei Yue, Zikun Su, Wangchunshu Zhou, Xiaobin Hu#, Shuicheng Yan# (* equal contribution, # corresponding author)
Conference on Empirical Methods in Natural Language Processing (EMNLP) 2026
A slow-fast co-evolution framework that teaches agents to improve through experience. OPD-Evolver combines a four-level memory hierarchy with outcome-calibrated attribution and privileged-hindsight distillation.
OPD-Evolver: Cultivating Holistic Agent Evolver via On-Policy Distillation
Guibin Zhang*, Xun Xu*, Yanwei Yue, Zikun Su, Wangchunshu Zhou, Xiaobin Hu#, Shuicheng Yan# (* equal contribution, # corresponding author)
Conference on Empirical Methods in Natural Language Processing (EMNLP) 2026
A slow-fast co-evolution framework that teaches agents to improve through experience. OPD-Evolver combines a four-level memory hierarchy with outcome-calibrated attribution and privileged-hindsight distillation.